Arjhine Ty

Notes from the work, written down.

Technical writing on the systems I build — the decisions behind them, what broke, and what I'd do differently next time.

Aug 2026

My hybrid extraction system beats both its halves. It still goes silent on half its failures.

V2 closed with a hybrid system that beats rules alone and the model alone on every metric — and one dominant failure, silent omission, that four separate fixes could not move below half of everything that goes wrong. V3 has spent four iterations against it since. The best result so far: three points narrower. Not closed. Here is the whole account, including the labelling bug that could have invalidated the headline number if an audit had not caught it.
Aug 2026

My model card says 1.000 F1. Do not believe it.

My first model card reports 1.000 F1. Here is why you should not believe it, what happened when I rebuilt the benchmark to stop flattering the model — scores fell, on purpose — and what the retraining running right now is meant to settle.

Aug 2026

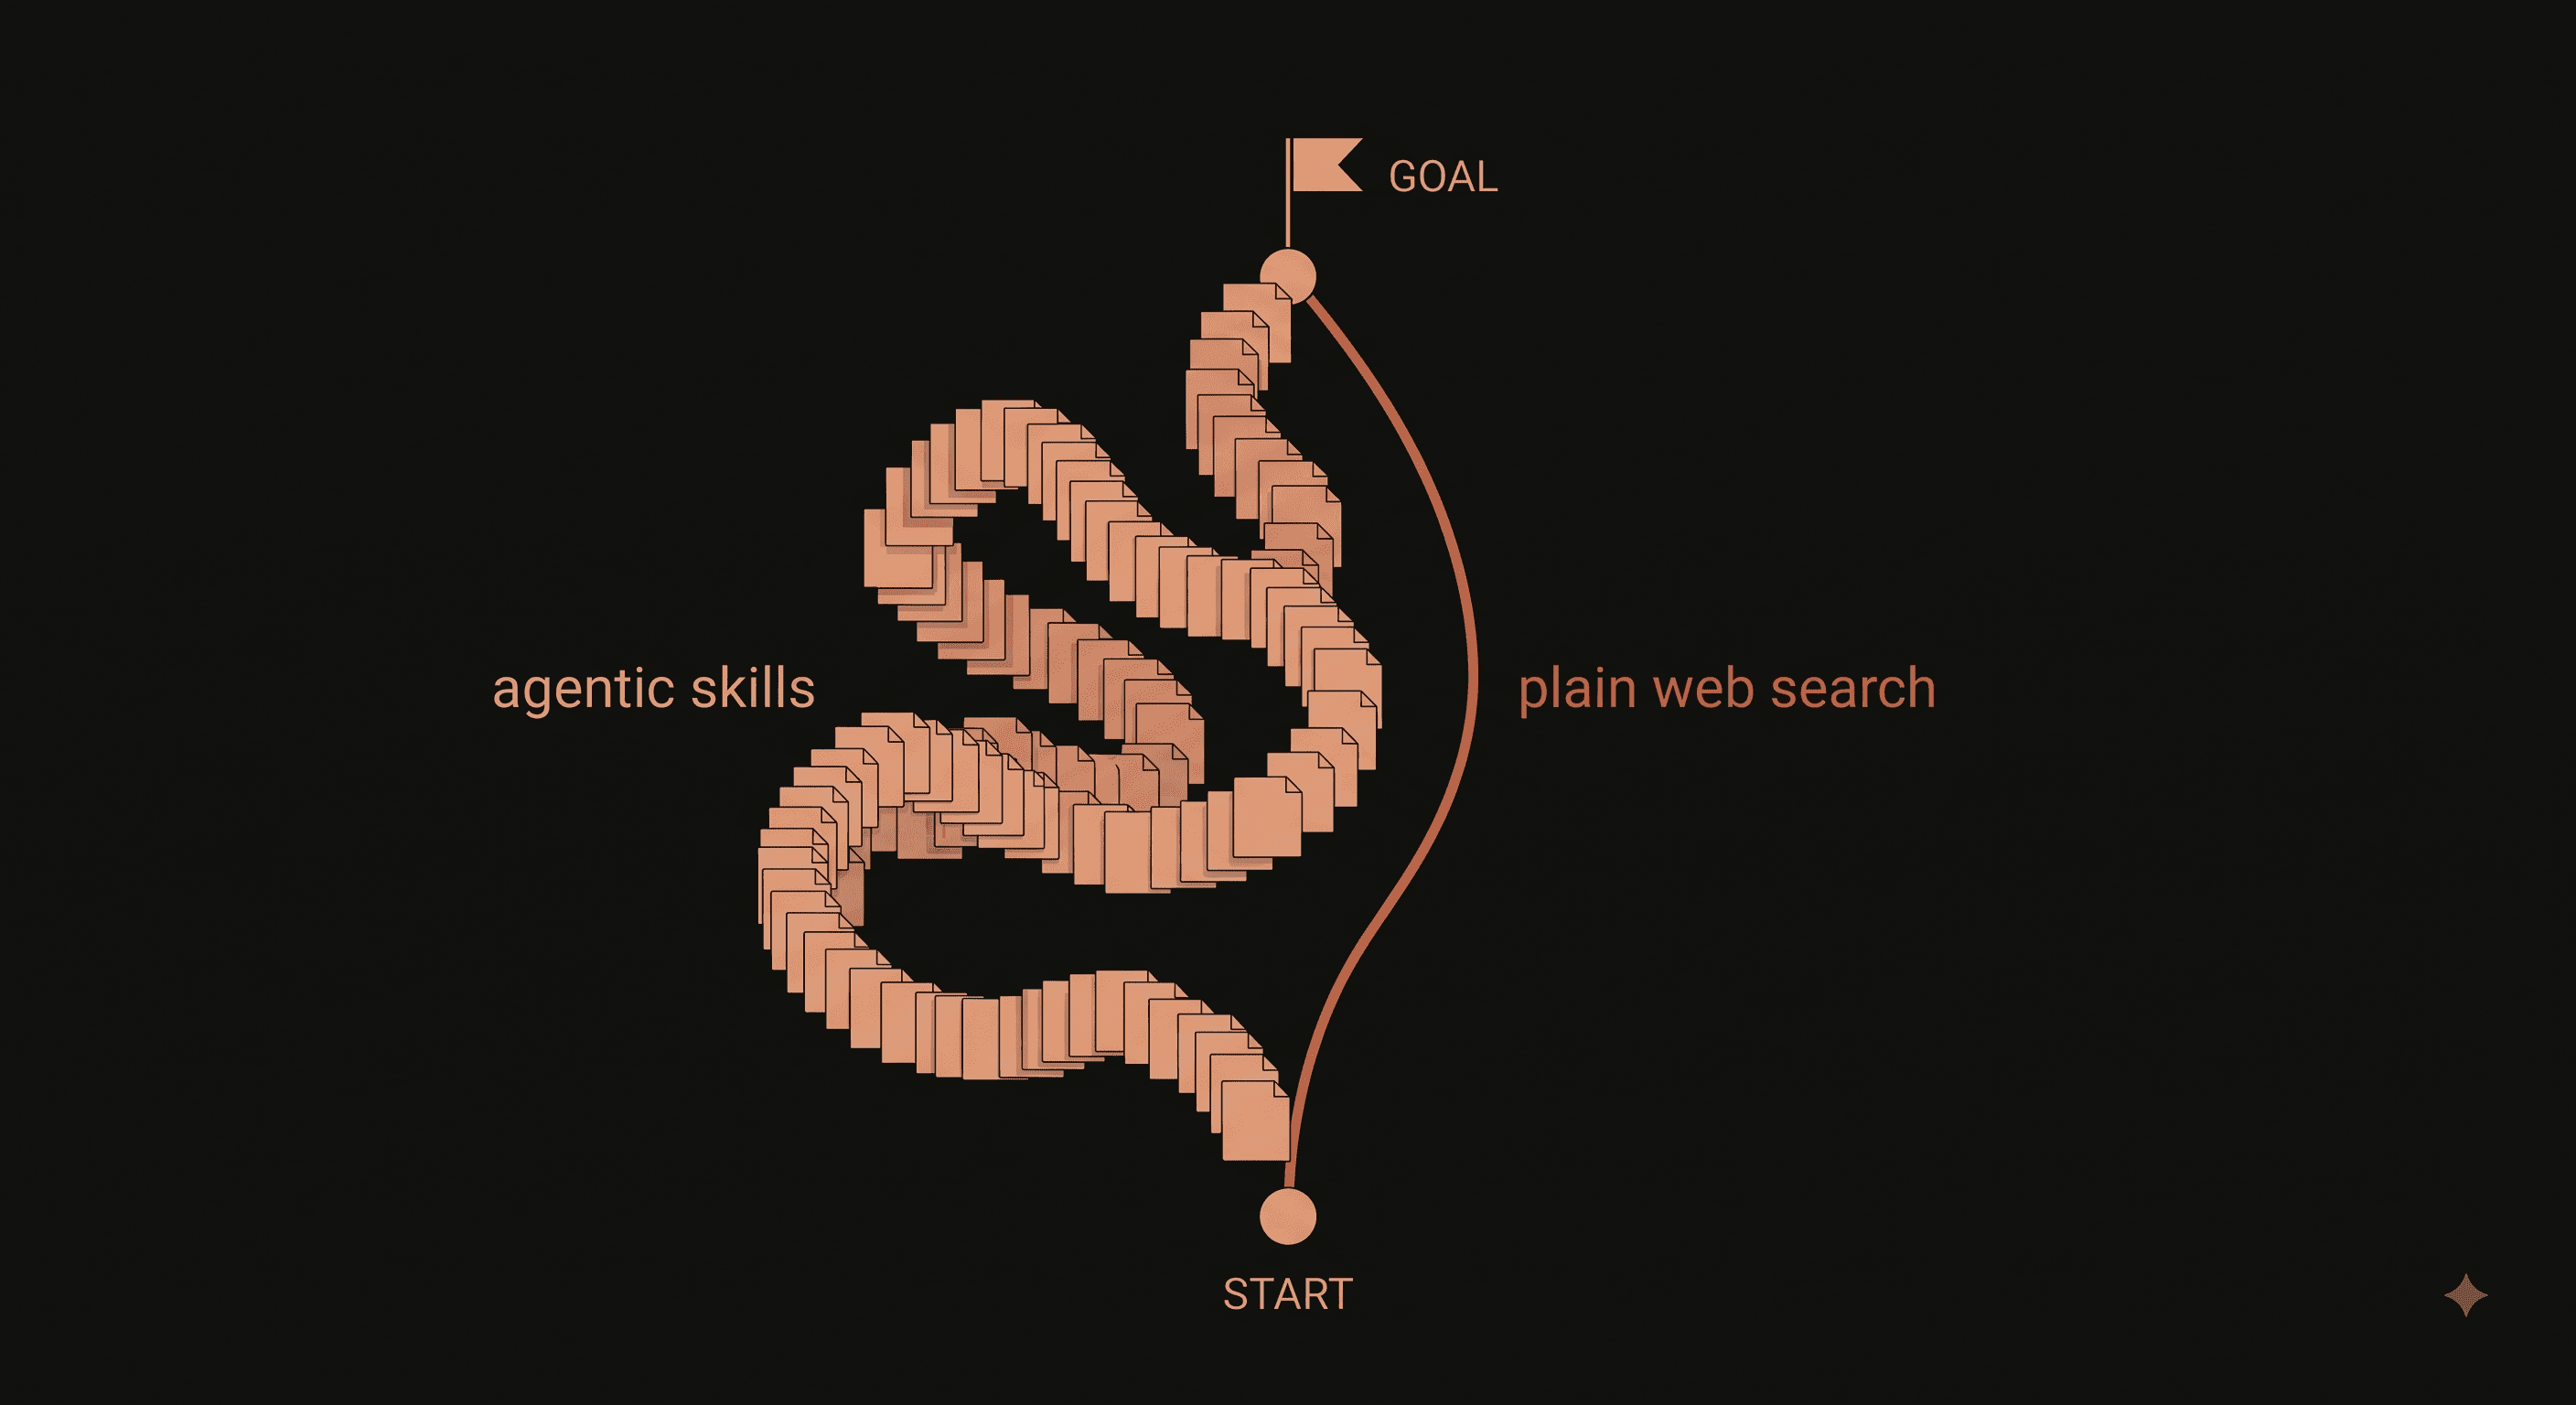
I benchmarked my own agentic skills against plain web search

120 agent runs across four arms says the skills I built did not beat an agent that can just search the web, and cost 2.6x the tokens doing it. Why the usual skills benchmark hides this, and the contamination bug that nearly invalidated the whole wave.

Aug 2026

I scaled my training data 10x. My model got worse at saying it didn't know something.

Scaling small-mind-companion's training data 10x looked like it made abstention worse — until I found a dedup bug that had collapsed 227 abstention examples down to 1, and an eval detector that could not recognize the model's own newly-correct phrasing. Fixing both uncovered a real third problem, over-hedging, which needed a separate fix. Where it landed: UAR at 70.0%, false-abstention on answerable questions down to 32.1%, and a reminder that a good-looking number is a reason to look harder, not stop.